Ed Pentz, our Executive Director, opened the 2026 Annual Meeting by introducing the theme: Good infrastructure is patient work. Crossref provides foundational infrastructure: an open, persistent scholarly record of metadata, relationships, and identifiers that thousands of tools and services build on. Maintaining that infrastructure and creating lasting value depends on sustained collective effort. True persistence requires active governance, long-term financial commitment, and organisational stewardship.
In 2022, we committed to balancing our working practices and environmental impact, and to openly reporting on those efforts. This is our third report on Crossref’s annual carbon footprint and reflects as much our emissions as it does our learning process. Travel remains the main area of our environmental impact. In 2025, our total emissions were 170 tCO2e, a 3% increase from 2024, with travel accounting for 85% of the total. A big change this year is that we have greater visibility into our AWS-related emissions. With the full transition of our metadata registry and content registration system to the cloud and significantly increased API use, we’re seeing higher carbon costs to host and run our services.
As we approach the end of 2026, research integrity remains a critical focus for the scholarly publishing ecosystem: fast technological advancements are constantly pushing the boundaries of integrity, impacting how everyone in this space interacts with the scholarly record.
Crossref members register around 37,000 records daily. All this metadata is openly shared with the global scholarly community through our free APIs. We receive over two billion calls to our API each month, signalling its use by hundreds of tools and services worldwide, supporting the discovery and assessment of scholarly metadata. As part of a new series in our blog, we will spotlight the diversity of tools and integrations that rely on Crossref metadata to serve the scholarly community. In this initial post, we chat to Luca Foppiano, the developer and maintainer of Grobid1, to learn about how Grobid uses Crossref metadata to improve the extraction and enrichment of bibliographic information from scholarly PDFs.
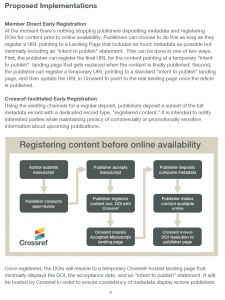
Crossref is proposing a process to support the registration of content—including DOIs and other metadata—prior to that content being made available, or published, online. We’ve drafted a paper providing background on the reasons we want to support this and highlighting the use cases. One of the main needs is in journal publishing to support registration of Accepted Manuscripts immediately on or shortly after acceptance, and dealing with press embargoes.
Proposal doc for community comment
We request community comment on the __proposed approach as outlined in this report.
Some examples of what we’d like to know:
Are you aware of the issues outlined in this proposal?
Are you aware of the funder and institutional requirements for authors to take action on acceptance of manuscripts for publication in journals?
Do you think the proposed solution and workflows are reasonable?
Are you likely to update your workflow to register content early?
If you are likely to update your workflow, how long do you estimate it will take?
Any other general comments, questions or feedback on anything raised in this document.
Please send comments, feedback and questions to me, Ginny, at feedback@crossref.org. The deadline for comments is February 4th. Thanks!
Related reading
Blog
Community responses to our proposal for early content registration