On behalf of the Nominating Committee, I’m pleased to share the slate of candidates for the 2026 board election. Every active member organisation is invited to submit a ballot to elect the incoming board class.
We’re providing a summary of the board’s July 2026 meeting. The July board meeting is our only in-person meeting. The board gathers for two days of strategic thinking and long-range planning, as well as conducting annual board business. This year, we focused on allocating surplus funds we have on hand to invest in a three-year project to redesign the content system. In a related discussion, we decided to lower content registration fees starting in 2027 because we’ve had a demonstrated history of generating surpluses, exceeding what we need to run Crossref. We also discussed the board structure, as part of our regular review of stakeholder governance. And we conducted annual board business, such as approving the audited financial statements and reviewed our risk register and mitigation plans.
The resolutions are available on the dedicated section of our website, which also lists the members of the Board and offers further information about our governance.
We also managed to squeeze in watching a World Cup game over dinner.
Starting today, funder names deposited in Crossref metadata without an identifier will be matched to ROR IDs, to support an open and connected Research Nexus. Funding information is an increasingly important part of the scholarly record. The improved matching strategy supports researchers, funders, institutions, and meta-researchers, who rely on that information to understand how research is supported and what outcomes that support produces.
Strengthening Scholarly Publishing in Africa is a collaborative webinar series bringing together ASSAf, Crossref, DOAJ, EIFL, and PKP to share practical guidance, resources, and approaches for strengthening the publishing ecosystem in the region. This series responds to the growing interest in open access, digital publishing, stronger editorial practices, and greater visibility of research publishing across Africa. Each partner organisation has long experience of building that capacity in the area of their expertise. In this series, we’re coming together to offer a more holistic learning experience to the community of African publishers, putting different aspects of the publishing process in their broader context.
If you take a peek at our blog, you’ll notice that metadata and community are the most frequently used categories. This is not a coincidence – community is central to everything we do at Crossref. Our first-ever Metadata Sprint was a natural step in strengthening both. Cue fanfare!. And what better way of celebrating 25 years of Crossref?
We designed the Crossref Metadata Sprint as a relatively short event where people can form teams and tackle short problems. What kind of problems? While we expected many to involve coding, teams also explored documenting, translating, researching—anything that taps into our open, member-curated metadata. Our motivation behind this format was to create a space for networking, collaboration, and feedback, centered on co-creation using the scholarly metadata from our REST API, the Public Data File, and other sources.
What have we learned in planning
The journey towards the event was filled with valuable lessons and learnings from our community. Our initial call received submissions from 71 people, which was exciting but presented the first challenge: we felt our event would work better with a relatively smaller group. An additional challenge we faced was the enthusiasm from people from different regions of the world who were eager to join, but needed support to attend in person. It reminded us how global our community is, and how important it is to think about different ways of making participation possible, especially in future events.
We also wanted to make sure that participation wasn’t limited by technical background. The selection process included a preliminary review by several members of our team to bring in a mix of perspectives and reduce bias. The event welcomed participants from all kinds of expertise levels, including colleagues who had never worked with APIs before. We sought to provide common ground for all with several group calls, where we presented introductions to our tools and used the opportunity to collect requests about tools, specific data, and questions from the participants that could enhance their preparation during the sprint.
At the Crossref Metadata Sprint
I’ve recently stumbled upon the following quote from a recognized data scientist:
Numbers have an important story to tell. They rely on you to give them a clear and convincing voice. (Stephen Few) 1
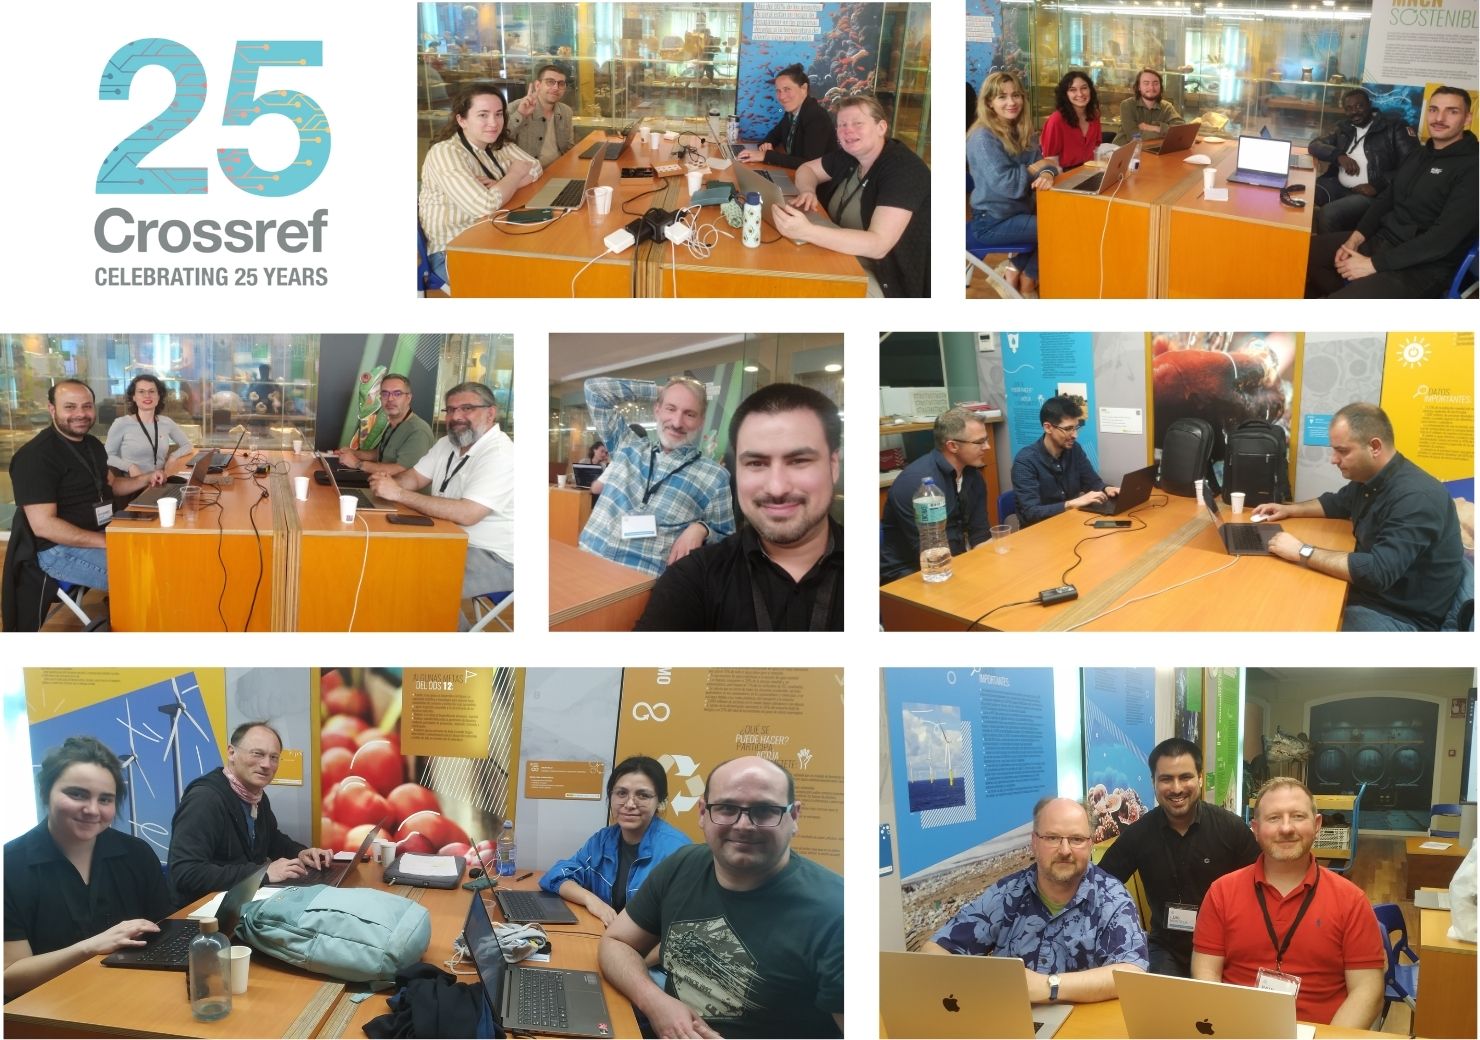
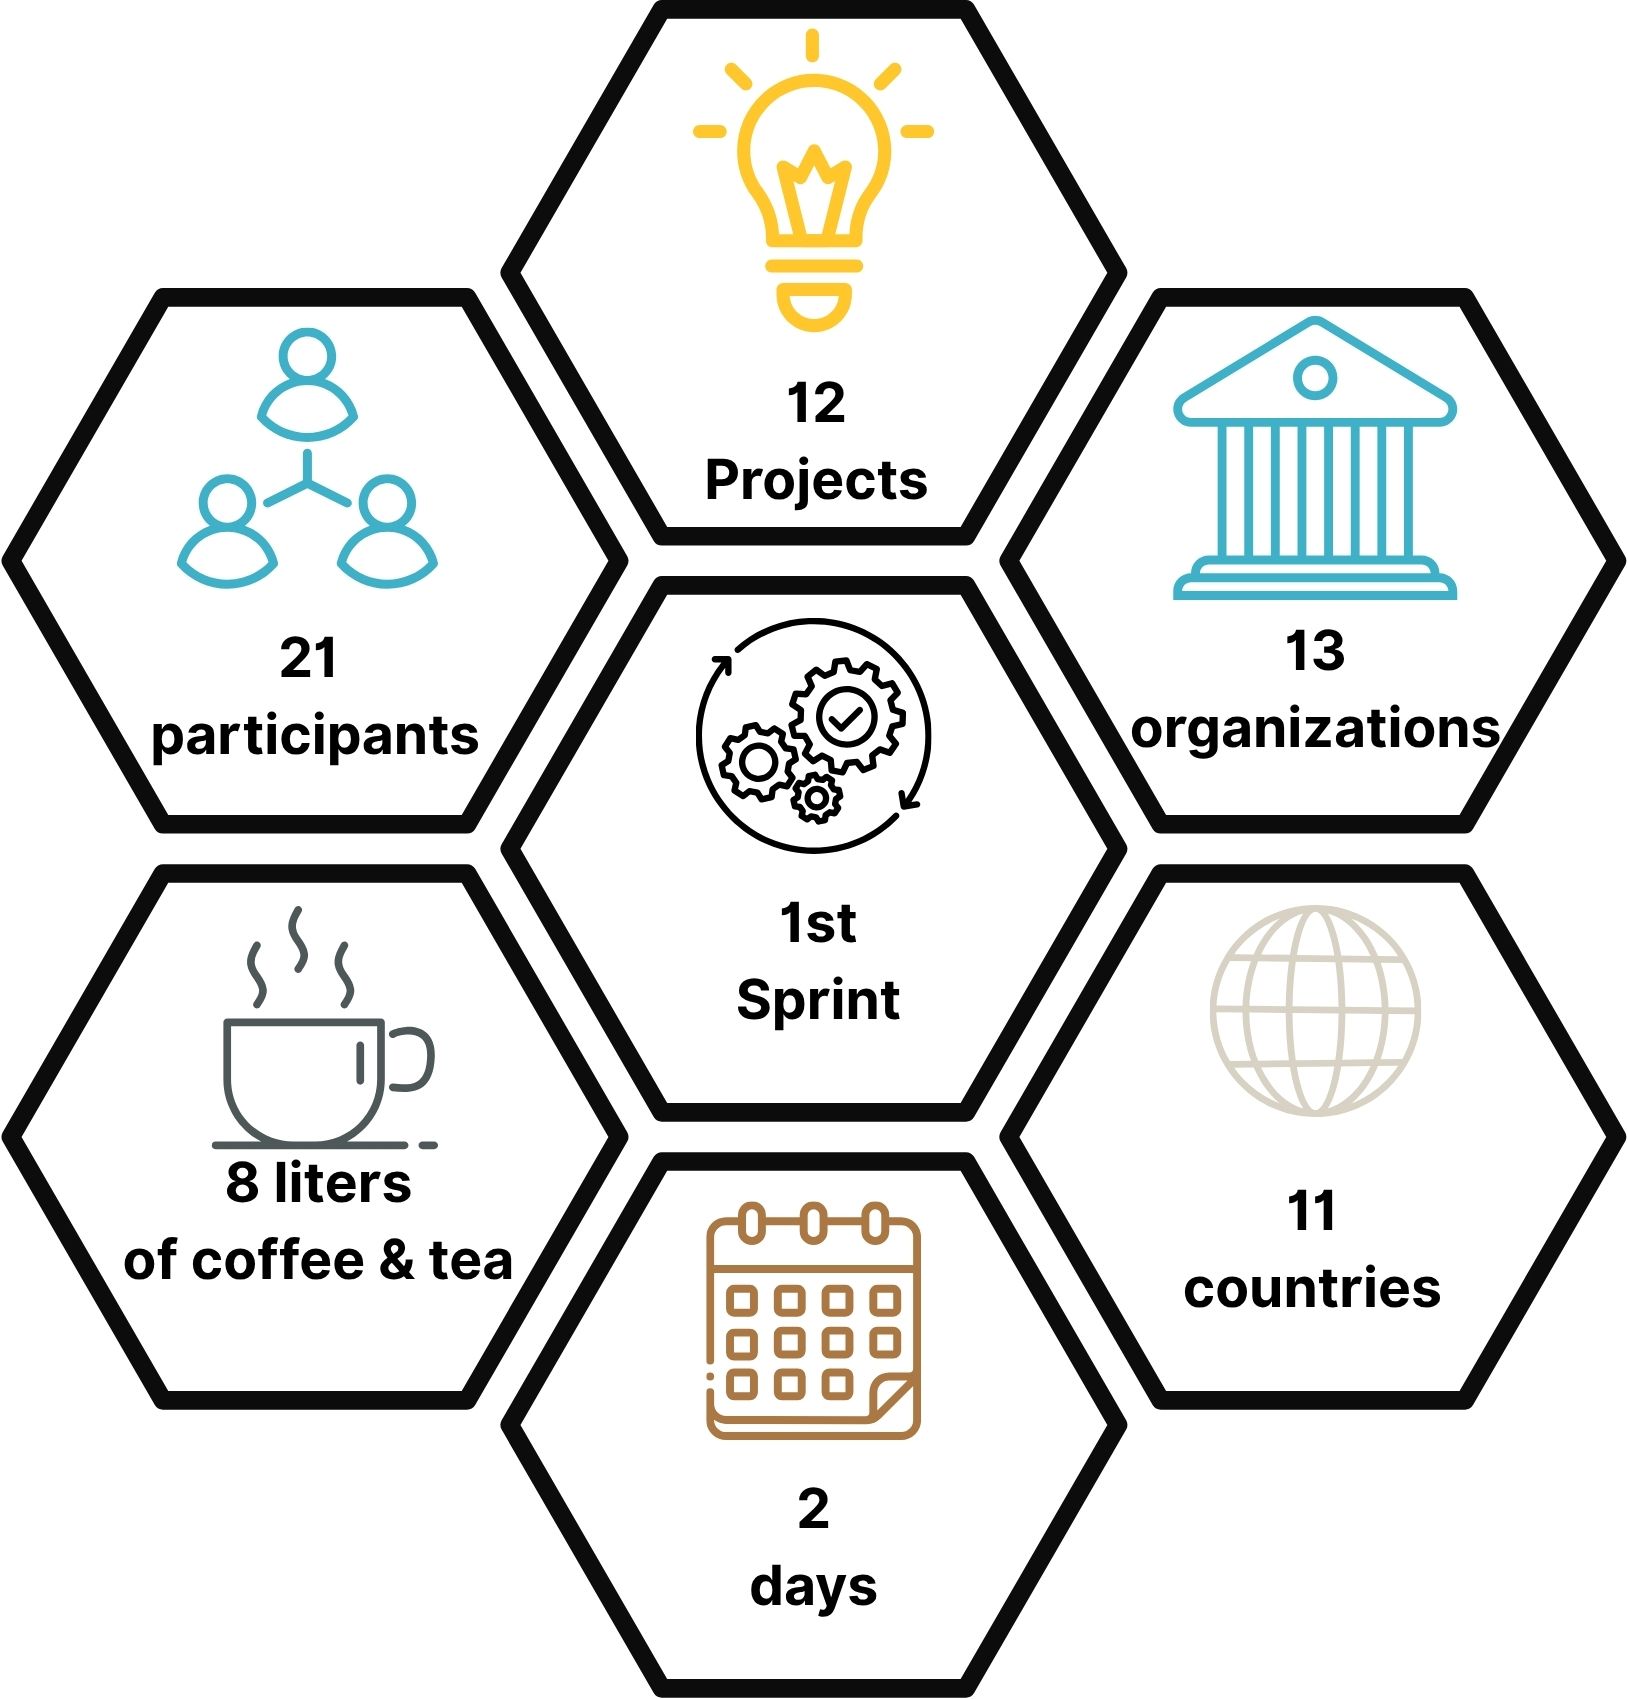
It made me think that we can replace numbers for metadata and the idea still holds. Surrounded by the paleontological collections of the National Museum of Natural History, on 8th of April in Madrid, 21 participants and 5 Crossref staff came together to work on twelve different projects. These ranged from improvements to our Public Data file formats and exploring metadata completeness, to tackling multilingual metadata challenges, understanding citation impact for retracted works, and connecting Retraction Watch metadata with other knowledge graphs metadata.
The different teams that participated in the first Crossref Metadata Sprint.
The initial hours were the most energetic (but not chaotic!) as most of the participants had the chance to interact in person for the first time, ideas were exchanged, and pre-formed groups became more stable (however, one of the advantages of the format is that teams don't have to be rigid). Twelve coffee- and tea-powered projects started taking shape, a few of which are part of larger ideas under development. By the end of the second day, we saw:
Author changes between preprints and published articles.
Coverage of funding information by publisher.
Enriching citations with Crossref metadata.
Funding metadata completeness.
Improvement to the Public Data File.
Interoperability between Crossref DOIs and hash-based identifiers.
University of Tetova’s metadata coverage.
Retraction Watch data mash-up.
Perspective about AI-driven multilingual metadata.
Public Data File in Google Big Query.
Visibility of retractions across citations.
Visualising Crossref geographic member data.
Our team worked as part of some of these projects, providing valuable insights and feedback to the participants. We ended the first session with a group dinner and re-energised for the second day, which started with everybody fully immersed in their tasks. As we approached the conclusion, the groups started preparing some quick slides for a short presentation (that you can find here).
Our team and the participants left excited and looking forward to the next opportunity to collaborate. We certainly see the potential of recreating these spaces, and we’ll work on future editions in a different location. All of the project summaries and notes will remain stored in our metadata sprint Gitlab repo. Would you like to know more about any of these ideas? Let us know in the comments.
The first Crossref Metadata Sprint in a nutshell
Participants
None of this would’ve been possible without our enthusiastic participants. Huge thanks to everyone! Here is the full list of those who attended our inaugural Sprint: